

Original Feishu document · Source revision 21
💡
Mechanisms lesson: Robot arms are typically fixed to a base, whereas humanoid and mobile robots must simultaneously handle balance, foot placement, collisions, contact transitions, and whole-body coordination. A high-level VLA cannot directly replace kilohertz-level whole-body control.
Learning Objectives
After completing this lesson, you should be able to interpret floating-base dynamics, centroidal dynamics, contact constraints, and motion imitation objectives; distinguish model-based whole-body control, learned whole-body control models, Behavior Foundation Models, reinforcement learning motion skills, and high-level VLA commands; and understand the roles of privileged learning, cross-embodiment training, domain randomization, and sim-to-real transfer in humanoid control.
1. A Floating-Base System Has No Fixed Support
Interpretation: The inertia, gravity, Coriolis, and other bias terms of the robot’s entire body are jointly balanced by actuated joint torques and generalized contact forces transmitted through all contact points.
Derivation: Begin with Lagrangian rigid-body dynamics. The selection matrix S indicates that the floating base has no direct actuators, while foot and hand contacts map environmental forces into generalized coordinates through the transpose of the Jacobian.
2. Centroidal Dynamics: A Low-Dimensional Skeleton of Whole-Body Motion
Interpretation: The robot’s mass multiplied by its center-of-mass acceleration equals the resultant of all contact forces and gravity.
Derivation: Apply Newton’s second law to every rigid body of the robot and sum the equations. Internal joint forces cancel in pairs, leaving only external contact forces and gravity.
The change in angular momentum satisfies:
Interpretation: The rate of change of angular momentum about the center of mass equals the sum, over all contacts, of the moment generated by each contact force relative to the center of mass plus any external pure torque applied at that contact point.
Derivation: Sum the angular-momentum equations for every rigid body in the system. Internal joint torques cancel in pairs, leaving only moments from external contacts. The moment arm of contact force f_i is the contact position r_i minus the center of mass c. If the foot or hand can also transmit a pure couple, tau_i is added separately.
These two equations explain why foot placement, contact forces, and upper-body motion all affect balance.
2.1 ZMP and Capture Point: Applicability Limits of Low-Dimensional Balance Metrics
Under the linear inverted pendulum approximation, assuming approximately constant center-of-mass height and small changes in angular momentum, the ground zero-moment point can be written as:
Interpretation: The horizontal ZMP position equals the horizontal center-of-mass position minus the center-of-mass height divided by gravitational acceleration, multiplied by the horizontal center-of-mass acceleration.
Derivation: Simplify the robot to a point mass at a fixed height and impose moment balance about the ground support point. The horizontal inertial force and gravity jointly determine the resultant force’s line of action and its intersection with the ground. Rearranging yields this equation. Under these assumptions, the ZMP lying within the support polygon is a feasibility condition, not sufficient proof of stability for arbitrary three-dimensional motions.
If the current foothold cannot arrest the divergent motion, the support must be changed through the next foot placement. The capture point of the linear inverted pendulum is:
Interpretation: The capture point equals the current horizontal center-of-mass position plus the horizontal center-of-mass velocity divided by the inverted pendulum’s natural frequency; the natural frequency is determined by gravity and center-of-mass height.
Derivation: The horizontal dynamics of a fixed-height linear inverted pendulum can be decomposed into convergent and divergent modes. After combining position and velocity into xi, xi represents the ideal support location that would arrest the divergent mode if the support point were placed there. Real robots are additionally constrained by step length, friction, swing-leg timing, and angular momentum, so this is a foot-placement heuristic rather than an unconditionally reachable point.
Formula Visualization|ZMP, Capture Point, and the Next Foot Placement
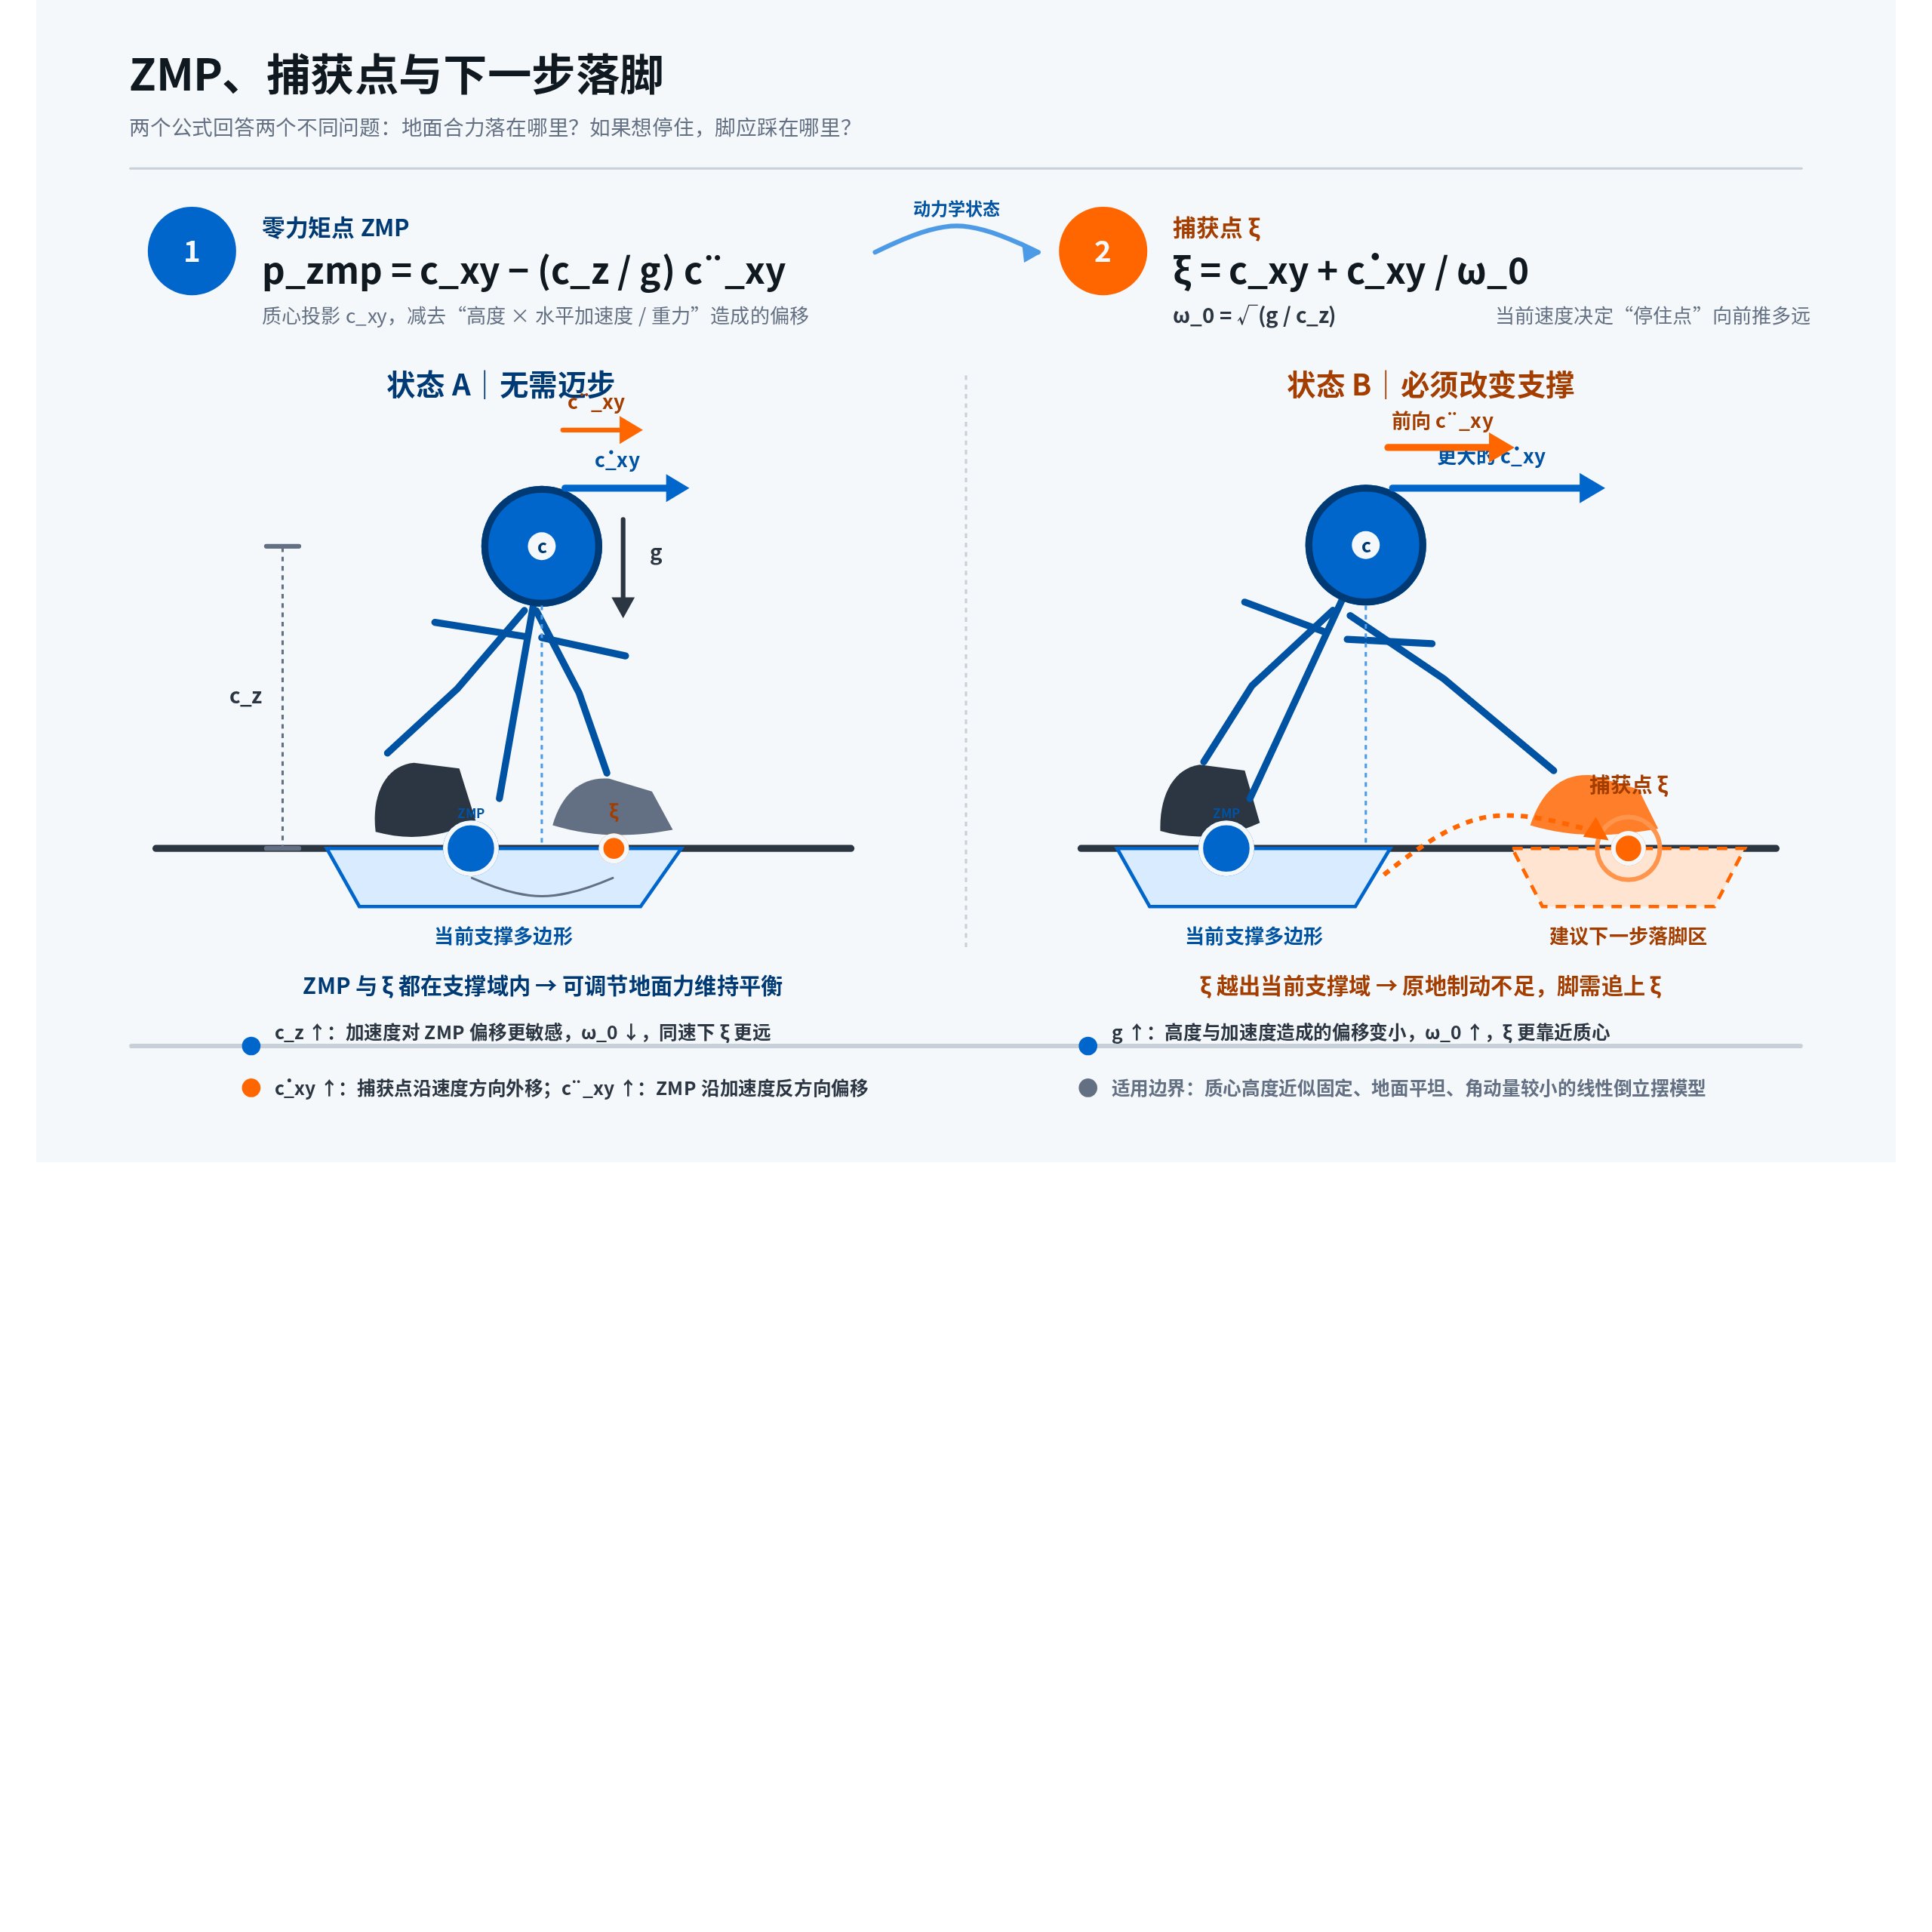
The value of these two metrics lies in compressing whole-body balance into interpretable low-dimensional quantities; their danger lies in making users forget the underlying assumptions. Rapid upper-body motion, hand support, variable center-of-mass height, and strong contact impacts all require a return to full centroidal momentum dynamics or whole-body dynamics.
3. The Contact Plan Determines Whether the System Can Execute a Motion
Preventing the foot from slipping requires the friction constraints to be satisfied:
Interpretation: The tangential contact force cannot exceed the coefficient of friction multiplied by the normal force, and the ground can only push the robot—it cannot pull the robot downward.
Derivation: These are the Coulomb friction cone and unilateral contact constraints. If a motion policy demands horizontal acceleration beyond the friction cone, the real robot will slip and fall even if the joint trajectory looks plausible in an animation.
4. How Whole-Body Control Combines Multiple Tasks
One common formulation is a constrained quadratic program:
Interpretation: Subject to floating-base dynamics, zero contact-point acceleration, friction feasibility, and actuator torque limits, find joint accelerations, torques, and contact forces that minimize the weighted acceleration errors of all task-space objectives.
Derivation: Second-order task-space kinematics state that end-effector acceleration equals the Jacobian multiplied by joint acceleration plus the Jacobian derivative term. Express the center-of-mass, torso, hand, and foot objectives as quadratic errors, then add whole-body dynamics, fixed-contact constraints, friction cones, and torque limits to obtain a constrained quadratic program. If tasks have strict priorities that cannot be compromised, hierarchical QP should be used rather than approximating priorities solely through extreme weights.
5. What Reinforcement Learning Motion Policies Learn
A low-level motion policy typically learns:
Interpretation: The low-level motion policy generates the action at the current time step from current onboard observations, motion commands, and an estimate of the environmental context.
Derivation: Formulate robot motion as a partially observable decision process: o_t contains proprioceptive state, contact information, and available exteroception; c_t specifies the target velocity, pose, or skill; and z_t summarizes terrain, payload, and dynamics variations. The policy learns a mapping from these conditions to an action distribution. Actions may be joint targets, joint increments, or constrained torques.
Actions may be target joint positions, joint increments, or torques. The reward combines velocity tracking, pose, energy consumption, smoothness, foot slippage, and fall penalties. In practice, reward design defines what it means for the robot to “walk properly.”
6. Imitation Learning and the DeepMimic Approach
Motion imitation commonly combines a reference motion with task objectives:
Interpretation: The reward at each step is a weighted sum of rewards for pose, velocity, end-effector position, center-of-mass tracking, and other objectives.
Derivation: This is a weighted scalarization of a multi-objective cost. Changing the weights changes the optimal behavior: overemphasizing pose can sacrifice disturbance recovery, while overemphasizing velocity can produce unnatural or high-impact gaits.
7. Privileged Learning and Online Adaptation
A simulation teacher can observe the true terrain, friction, and external forces, whereas the deployed policy has access only to onboard sensors. An adaptation module estimates the environmental context from history:
Interpretation: From a recent history of observations and actions, the adaptation module estimates the latent context of the current terrain, payload, or dynamics.
Derivation: Unknown physical parameters leave traces in the state changes caused by past actions. If the history contains sufficient excitation, the model may identify context that is useful for control.
8. From RMA to Modern Humanoid Policies
| Approach | Core mechanism | Evaluation focus |
|---|---|---|
| DeepMimic | Reference-motion imitation and task rewards | Motion quality and disturbance recovery |
| RMA | Privileged teacher and rapid environmental adaptation | Abrupt dynamics changes and out-of-range parameters |
| Large-scale locomotion RL | Parallel simulation, randomization, and curriculum learning | Real-world terrain and contact impacts |
| Humanoid whole-body imitation | Retargeting human motion data to robots | Feasibility, balance, and morphological differences |
| High-level VLA + low-level skills | Language/vision subgoals invoke motion skills | Interface frequency, failure detection, and safe switching |
8.1 Whole-Body Control Models and Behavior Foundation Models
A learned whole-body control model is typically conditioned on proprioceptive state, contact state, a reference motion, or high-level commands, and directly outputs joint targets or torques. It learns “how to make the entire body execute a reference or command stably and coordinately,” not “how the world will change after an action.” It is therefore a policy and control model, not a world model from Route B.
Behavior Foundation Model (BFM). This term emphasizes training reusable whole-body behavior priors on large-scale, heterogeneous human and robot motion data. Recent work has begun to scale motion-data diversity, policy capacity, and the number of online rollouts simultaneously, allowing a single control model to cover more motion styles, coordination among body parts, and control conditions. A “large model,” however, does not automatically guarantee contact feasibility; stability still depends on high-frequency feedback, state estimation, actuator models, and validation on real hardware.
| Representative approach | Primary scaling axis | Key limitation |
|---|---|---|
| HoloMotion-1 | Uses a mixed motion corpus consisting of in-the-wild video reconstruction, motion capture, and internal data to train a zero-shot whole-body motion-tracking model | Broader motion coverage does not mean that foot contacts, torque peaks, and long-duration thermal loads are deployable |
| XHugWBC | Trains a single control policy across humanoid embodiments through physically consistent morphology randomization and semantically aligned observation/action spaces | Zero-shot transfer must be validated on unseen robots, real actuator variations, and out-of-distribution contact conditions |
| Scaling BFM | Jointly scales reference-motion diversity, on-policy rollouts, and Humanoid Transformer capacity | Control experiments over data, model scale, and training compute are needed to determine which scaling axis produces the gains |
| ReactiveBFM | Connects generative motion planning to a high-frequency tracking loop and learns error recovery through prefix sampling and asynchronous replanning | Exposure bias, latency, and state errors between the planner and controller remain decisive risks |
Correct interface. A BFM or learned WBC can serve as a “motion cerebellum,” receiving velocity, pose, end-effector trajectories, text-generated motion references, or skill tokens. Classical WBC/QP can still act as a constraint projection, safety layer, or fallback. Evaluations should separately report reference tracking, disturbance recovery, cross-motion generalization, cross-embodiment transfer, contact constraints, and hardware constraints rather than substituting demonstration videos for control evidence.
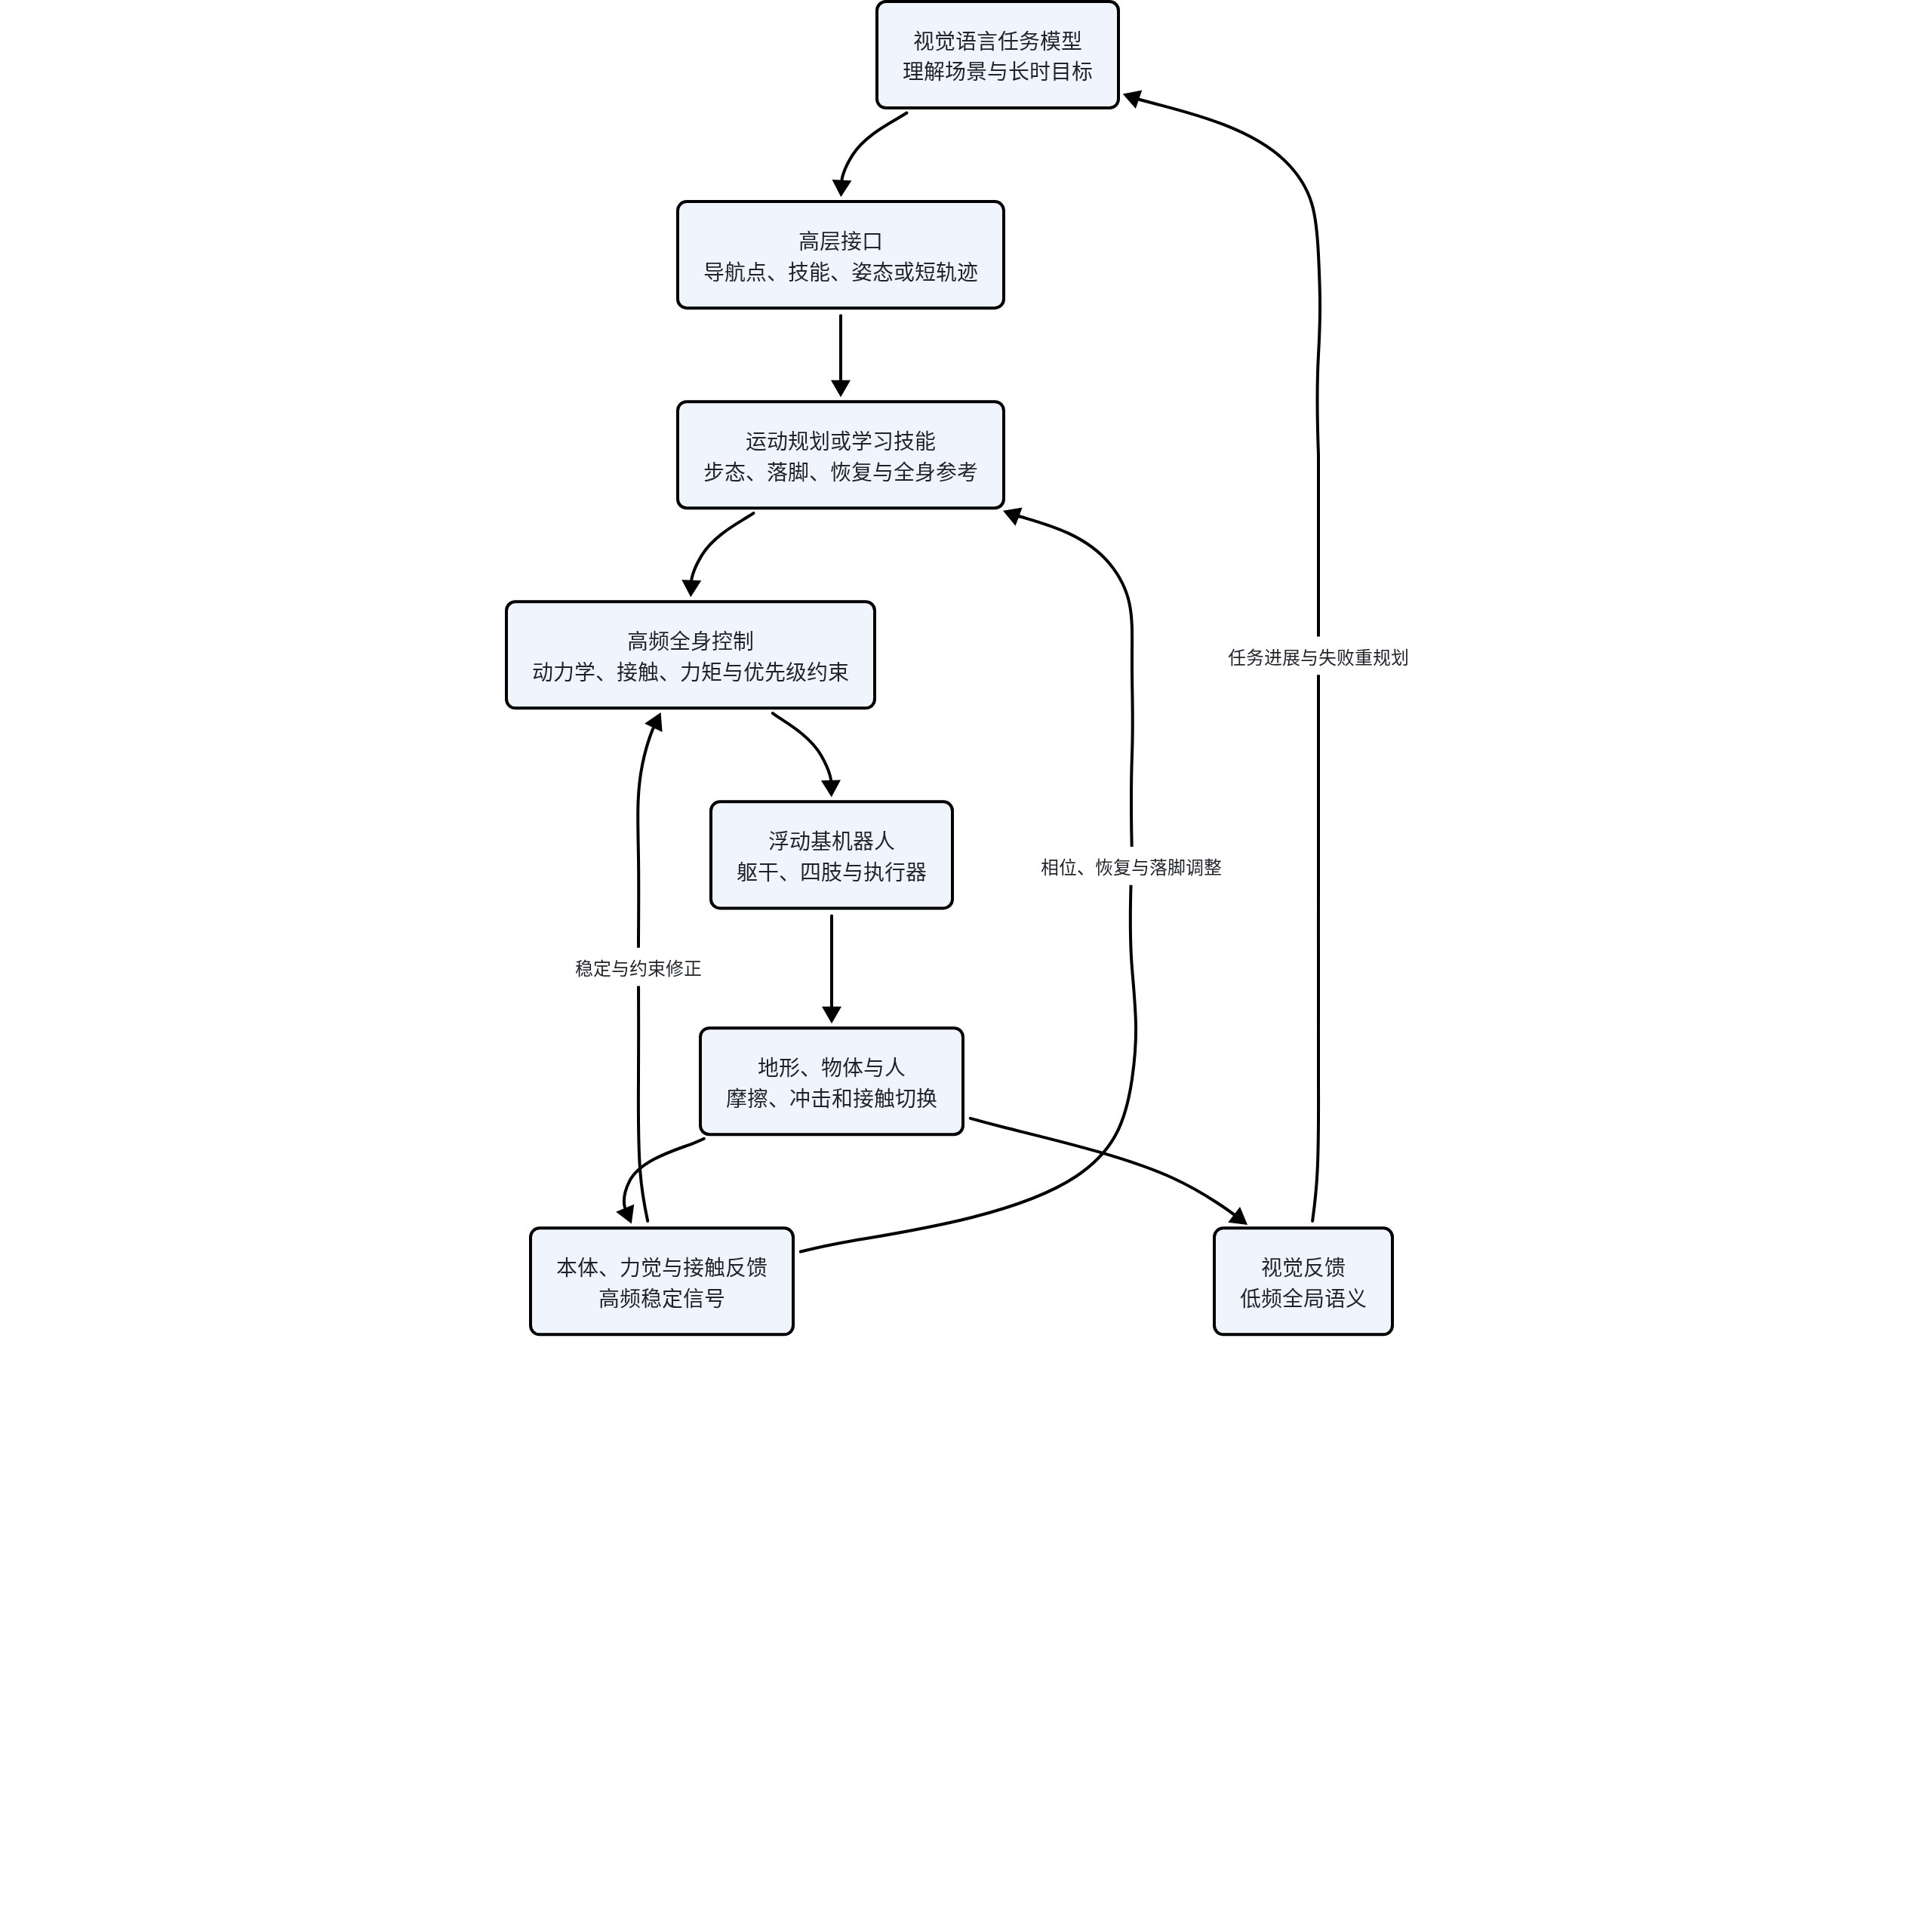
9. The Proper Boundary Between VLA and Whole-Body Control
A high-level model is well suited to outputting target objects, navigation waypoints, body poses, skill tokens, or short-horizon end-effector trajectories. The low-level system is responsible for dynamic balance, foot contacts, and torque tracking. Having a VLA directly output whole-body torques from low-frequency visual input shifts the entire burden of stability, latency, and hardware variation onto the data.
10. Minimal Experiment
Two-level model. First use a linear inverted pendulum to validate the ZMP, capture point, and foot-placement recovery. Then use a simplified biped model with a floating base, bilateral foot contacts, and joint-torque limits to validate the whole-body control interface. Both model levels share the same set of high-level velocity and turning commands.
| Experimental dimension | Setup | Question to answer |
|---|---|---|
| Control architecture | Open-loop reference trajectory, model-based MPC/WBC, RL skill, and RL skill with a WBC safety layer | Does balance come from the reference motion, feedback model, learned policy, or constraint projection? |
| Contact conditions | Friction, ground height, compliance, and foot-ground coefficient of restitution | Is the motion dynamically feasible, or feasible only under the nominal contact model? |
| Hardware conditions | Payload, joint gains, torque saturation, control latency, and dropped observation frames | Does sim-to-real degradation originate from the model, actuators, or timing? |
| Disturbances | Pushes with different directions, magnitudes, durations, and phases; missed steps and trips | Does the policy apply ankle correction, hip correction, adjust foot placement, or request high-level replanning? |
| Interface frequency | High-level commands at 2, 5, 10, and 20 Hz; low-level control fixed at 500 Hz | How do overly slow high-level updates and overly rapid switching disrupt the closed loop? |
Recorded metrics. In addition to success rate and velocity error, report fall rate, recovery time, number of additional steps, ZMP/support-foot boundary violations, foot slippage, peak contact force, peak and RMS torque, mechanical power, number of joint-limit events, and a proxy for temperature rise.
Key ablations. Hold the high-level commands fixed while replacing only the low-level controller; hold the low-level controller fixed while changing only the high-level update frequency; freeze the adaptation context and shuffle the history; replace the human reference motion with a motion that performs the same task in a different style. These ablations are necessary to separate the respective contributions of task understanding, motion style, dynamics adaptation, and stable control.
11. Failure Modes
| Failure mode | Observable symptom | Root cause | Validation and remediation |
|---|---|---|---|
| Simulation contacts are too soft or have no delay | The real robot exhibits high-frequency foot vibration, impact peaks, and torque saturation | Contact stiffness, actuator bandwidth, and control timing are mismatched | Replay real timestamps and force signals; sweep contact and latency parameters; reduce bandwidth and increase damping |
| Human motion cannot be retargeted | The motion looks similar visually, but the feet slip, joints hit their limits, or the center of mass leaves the feasible region | Differences in morphology, mass distribution, joint ranges, and contact timing are ignored | Add dynamic-feasibility optimization; report reference error and contact feasibility rather than relying only on videos |
| Mean velocity meets the target, but the policy is not deployable on hardware | Peak torque, power, temperature rise, or gear impacts remain beyond limits over long durations | The reward optimizes only task performance and energy consumption over short episodes | Add hardware constraints; run long-duration tests; report peaks, quantiles, and thermal-model results |
| High-level commands switch too quickly | A skill is interrupted before entering a stable phase, and the contact plan repeatedly flips | The interface lacks a minimum dwell time, completion criteria, and safe switching states | Add skill handshakes, hysteresis, and interruptible states; sweep the command frequency |
| Recovery policy overfits to disturbance direction | The robot recovers from pushes in trained directions but immediately fails under diagonal or sustained pushes or missed steps | The disturbance curriculum covers only limited directions, phases, and durations | Randomize disturbances hierarchically; report performance surfaces by direction and phase |
| VLA directly assumes responsibility for low-level stability | Whole-body torques become unstable together when the visual frame rate drops or network jitter occurs | Responsibilities are not separated between the low-frequency semantic model and high-frequency contact control | Have the VLA output goals or skills; keep proprioceptive and force feedback in the high-frequency skill/WBC loop |
12. Exercises
- Derive the center-of-mass linear-momentum equation from the whole-body Newton equations.
- Explain why similar joint trajectories do not guarantee feasible contact forces.
- Divide the responsibilities of the VLA, motion policy, and whole-body control for the task “walk forward and pick up an object.”
- Design an experiment to test whether the adaptation module genuinely identifies changes in friction.
- Define five safety and hardware metrics for a humanoid policy beyond success rate.
13. Paper Evidence Matrix
The following places classical balance control, whole-body control, imitation learning, rapid adaptation, and modern humanoid whole-body imitation within a single chain of evidence.
| Work | Paper fact | Authors’ interpretation | Course assessment |
|---|---|---|---|
| Kajita et al.|ZMP Preview Control | This work uses ZMP references and preview control with a linear inverted pendulum model to generate center-of-mass trajectories for bipedal walking. | The authors use future ZMP references to improve current center-of-mass control rather than relying only on instantaneous error feedback. | ZMP is a highly useful low-dimensional model, but assumptions such as fixed center-of-mass height and small angular momentum must be stated explicitly. |
| Sentis & Khatib|Whole-Body Control | This approach uses operational space and task priorities to organize multiple whole-body behaviors and contact constraints for floating-base robots. | The authors decompose complex behaviors into prioritized tasks while preserving dynamic consistency. | WBC does not learn semantic tasks; it projects high-level objectives into instantaneous commands that satisfy contact, torque, and priority constraints. |
| Peng et al.|DeepMimic | DeepMimic combines reference-motion imitation rewards with task rewards, learns multiple dynamic character skills, and demonstrates disturbance recovery. | The authors use reference motions to provide motion priors while retaining room for reinforcement learning to optimize task performance and recovery. | Imitation quality and physical robustness are separate metrics; human-like motion does not mean that contact forces, energy consumption, and hardware loads are deployable. |
| Hwangbo et al.|Dynamic Legged Skills | This work deploys dynamic quadrupedal locomotion policies on a real robot through large-scale simulation training and system modeling. | The authors emphasize the importance of actuator modeling, randomization, and high-frequency control for real-world dynamic skills. | The sim-to-real bottleneck often lies in actuators and timing; success should not be attributed to the network architecture alone. |
| Kumar et al.|RMA | RMA estimates environmental context from recent interaction history, enabling a quadruped policy to adapt rapidly to changes in terrain and dynamics. | The authors train a base policy with a privileged teacher, then have a deployment-time adaptation module recover context from the available history. | Evidence of adaptation should consist of recovery after abrupt parameter changes and history ablations, not latent clustering plots. |
| Fu et al.|HumanPlus | HumanPlus uses human motion data and hierarchical learning to enable humanoid robots to perform shadowing, imitation, and multiple whole-body tasks. | The authors transfer human priors to humanoid control and use low-level motion capabilities to support high-level task imitation. | Modern humanoid approaches are beginning to connect “feasible motion priors” with “task semantics,” but they still depend on stable low-level control, retargeting, and real-world safety validation. |
| HoloMotion-1 | Trains a humanoid motion foundation model on a large-scale mixed motion corpus for zero-shot whole-body motion tracking. | Reconstructing motion from in-the-wild video can substantially expand behavioral coverage beyond MoCap. | Reconstruction noise, contact feasibility, the long tail of motions, and real-hardware loads should all be audited. |
| XHugWBC | Trains a single cross-embodiment whole-body control policy through morphology randomization and semantic interfaces shared across robots. | A shared control model can absorb structural differences among multiple humanoid robots into a unified policy. | Real-world transfer to unseen embodiments, actuator-bandwidth differences, and safety degradation are more important than average simulation scores. |
| Scaling BFM / ReactiveBFM | The former studies joint scaling of behavior data, rollouts, and model capacity; the latter combines motion generation and high-frequency tracking into a reactive closed loop. | Whole-body control foundation models can progress from “reproducing references” to multi-condition behavior, recovery, and real-time replanning. | The contributions of planning, tracking, and recovery must be separated, with latency, tracking deviation, fall rate, and real-world disturbance tests reported. |
13.1 Primary Sources
- HoloMotion-1 Technical Report
- XHugWBC: Scalable and General Whole-Body Control for Cross-Humanoid Locomotion
- Scaling Behavior Foundation Model for Humanoid Robots
- ReactiveBFM: Reactive Closed-Loop Motion Planning Towards Universal Humanoid Whole-Body Control
14. Cross-Reading
Read together with F1 and F2. Whole-body stability ultimately remains a problem of feedback, latency, and contact. Center-of-mass metrics cannot replace foot-force measurements, friction modeling, and actuator bandwidth.
Read together with F3. The real-world capabilities of modern locomotion RL depend heavily on actuator identification, randomization, history-based adaptation, and time synchronization.
Read together with Routes A and D. The VLA is responsible for semantic goals and skill invocation, hierarchical planning handles long-horizon transitions, and low-level skills and WBC handle dynamic balance and instantaneous contact feasibility.
Read together with Route E. Human video and motion capture provide motion priors, but cross-embodiment retargeting must respect the humanoid robot’s morphology, mass properties, joints, contacts, and hardware limitations.