

Original Feishu Document · Source Revision 10
🔬
Paper Lab: A unified comparison of five mechanisms for incorporating human video into robot learning: representation pretraining, trajectory/point prediction, high-level planning, human motion retargeting, and test-time adaptation.
Unified Comparison Framework
| Dimension | Question |
|---|---|
| Human data | Action-free video, keypoints, motion capture, or demonstrations |
| Intermediate variable | Representation, trajectory, skill, pseudo-action, or fast memory |
| Robot supervision | How much action data and how many paired tasks |
| Alignment | Visual, object, event, temporal, or embodiment alignment |
| Evidence | Few-shot learning, cross-environment generalization, real-robot evaluation, and task holdouts |
1. R3M / VIP: Visual Representation Pretraining
Large-scale human video is used to learn temporally and linguistically relevant visual representations, which are then supplied to robot policies. The advantages are generality and simplicity; the limitation is that better representations do not amount to action supervision, and control gains depend on subsequent robot data.
2. MimicPlay: Human Video as a High-Level Plan
A high-level plan representation is learned from human demonstrations and executed by a low-level robot policy. This avoids directly mapping human actions to robot joints and emphasizes visual task progress and hierarchical division of labor.
3. ATM: Future Trajectories of Arbitrary Points
Future trajectories of image points are predicted from video, providing cues about objects and local motion. Trajectories are more compact than pixel generation, but the two-dimensional point motion must still be converted into robot-executable actions.
4. Video Generation as a Planning Space
Future videos or visual subgoals are generated under language conditioning and then followed by a robot policy. The advantage is the ability to leverage internet video; the risk is that generated futures may be physically inconsistent, unreachable, or incompatible with the target embodiment.
5. HumanPlus / OmniH2O: From Human Motion to Humanoid Robots
Human motion, motion capture, and retargeting are used to train humanoid robots. Because humanoid embodiments resemble the human body, motion alignment is more direct, but mass, contact, joint limits, and control stability still differ.
6. WAM-TTT: Writing Human Video into Behavioral Memory at Test Time
Rather than directly converting human video into actions, meta-training is used to learn “what kinds of human-side updates improve robot-task performance.” The key elements are the inner/outer loop and human–robot task correspondence.
7. Method Comparison
| Method | Intermediate variable | Robot data | Primary risk |
|---|---|---|---|
| R3M/VIP | Visual representation | Downstream policy data | Disconnect between representation and control |
| MimicPlay | High-level plan | Low-level execution | Grounding the plan in execution |
| ATM | Point trajectories | Action adaptation | 2D/3D geometry and contact |
| Video generation | Future visual states | Low-level following | Physical hallucination |
| HumanPlus | Human motion | Retargeting and control | Dynamics mismatch |
| WAM-TTT | Fast memory | Meta-training pairs | Memory contamination and synchronization assumptions |
8. Unified Experimental Protocol
- Fix the robot-data budget.
- Compare against a baseline that does not use human data.
- Add representations, trajectories, plans, pseudo-actions, and memory separately.
- Strictly hold out objects, environments, and task structures.
- Include temporally shuffled human videos and irrelevant-video controls.
- Report closed-loop robot success and recovery.
9. Lab Assignments
- Draw a “human data → intermediate variable → robot action” diagram for the six methods.
- Distinguish representation transfer from action transfer.
- Design an experiment on physical hallucinations in video.
- Compare the cross-embodiment assumptions for humanoid robots and robot arms.
- Design an incorrect-demonstration control for WAM-TTT.
- Create an evidence matrix that marks real-robot tasks and data-leakage risks.
Existing Topic Materials
E0|Data, Representation, and Cross-Embodiment Learning
D3|Memory and Test-Time Adaptation
Lab Deep Dive|Unified Formulation, Visualization, and Reproduction
Human video, robot trajectories, latent actions, and cross-embodiment co-training can be unified as representation learning conditioned on the data source and embodiment:
Interpretation: Given a recent observation window, the data-source identifier d, and the embodiment description e, the encoder extracts a shared representation z_t.
Derivation: The history window provides information about motion and task phase, d distinguishes supervision sources such as human videos and robot trajectories, and e describes the body and sensors. If z merely memorizes d or e without preserving task-relevant functionality, it will provide no transfer benefit on strictly held-out embodiments.
Interpretation: Given the shared representation and target embodiment e star, the decoder predicts the action, subgoal, or state change for that target embodiment.
Derivation: The shared representation must be reinterpreted as a concrete output through conditioning on the target embodiment. Setting e_star to a robot not seen during training and providing only a small amount of adapter data is a key experiment for testing whether cross-embodiment semantics genuinely exist.
Read this as: “First extract task-relevant states from observations originating from different sources and bodies, then decode actions, subgoals, or dynamics changes for the target robot.” The key question is not whether the latent space is shared, but whether sharing improves target-task performance under strict holdouts.
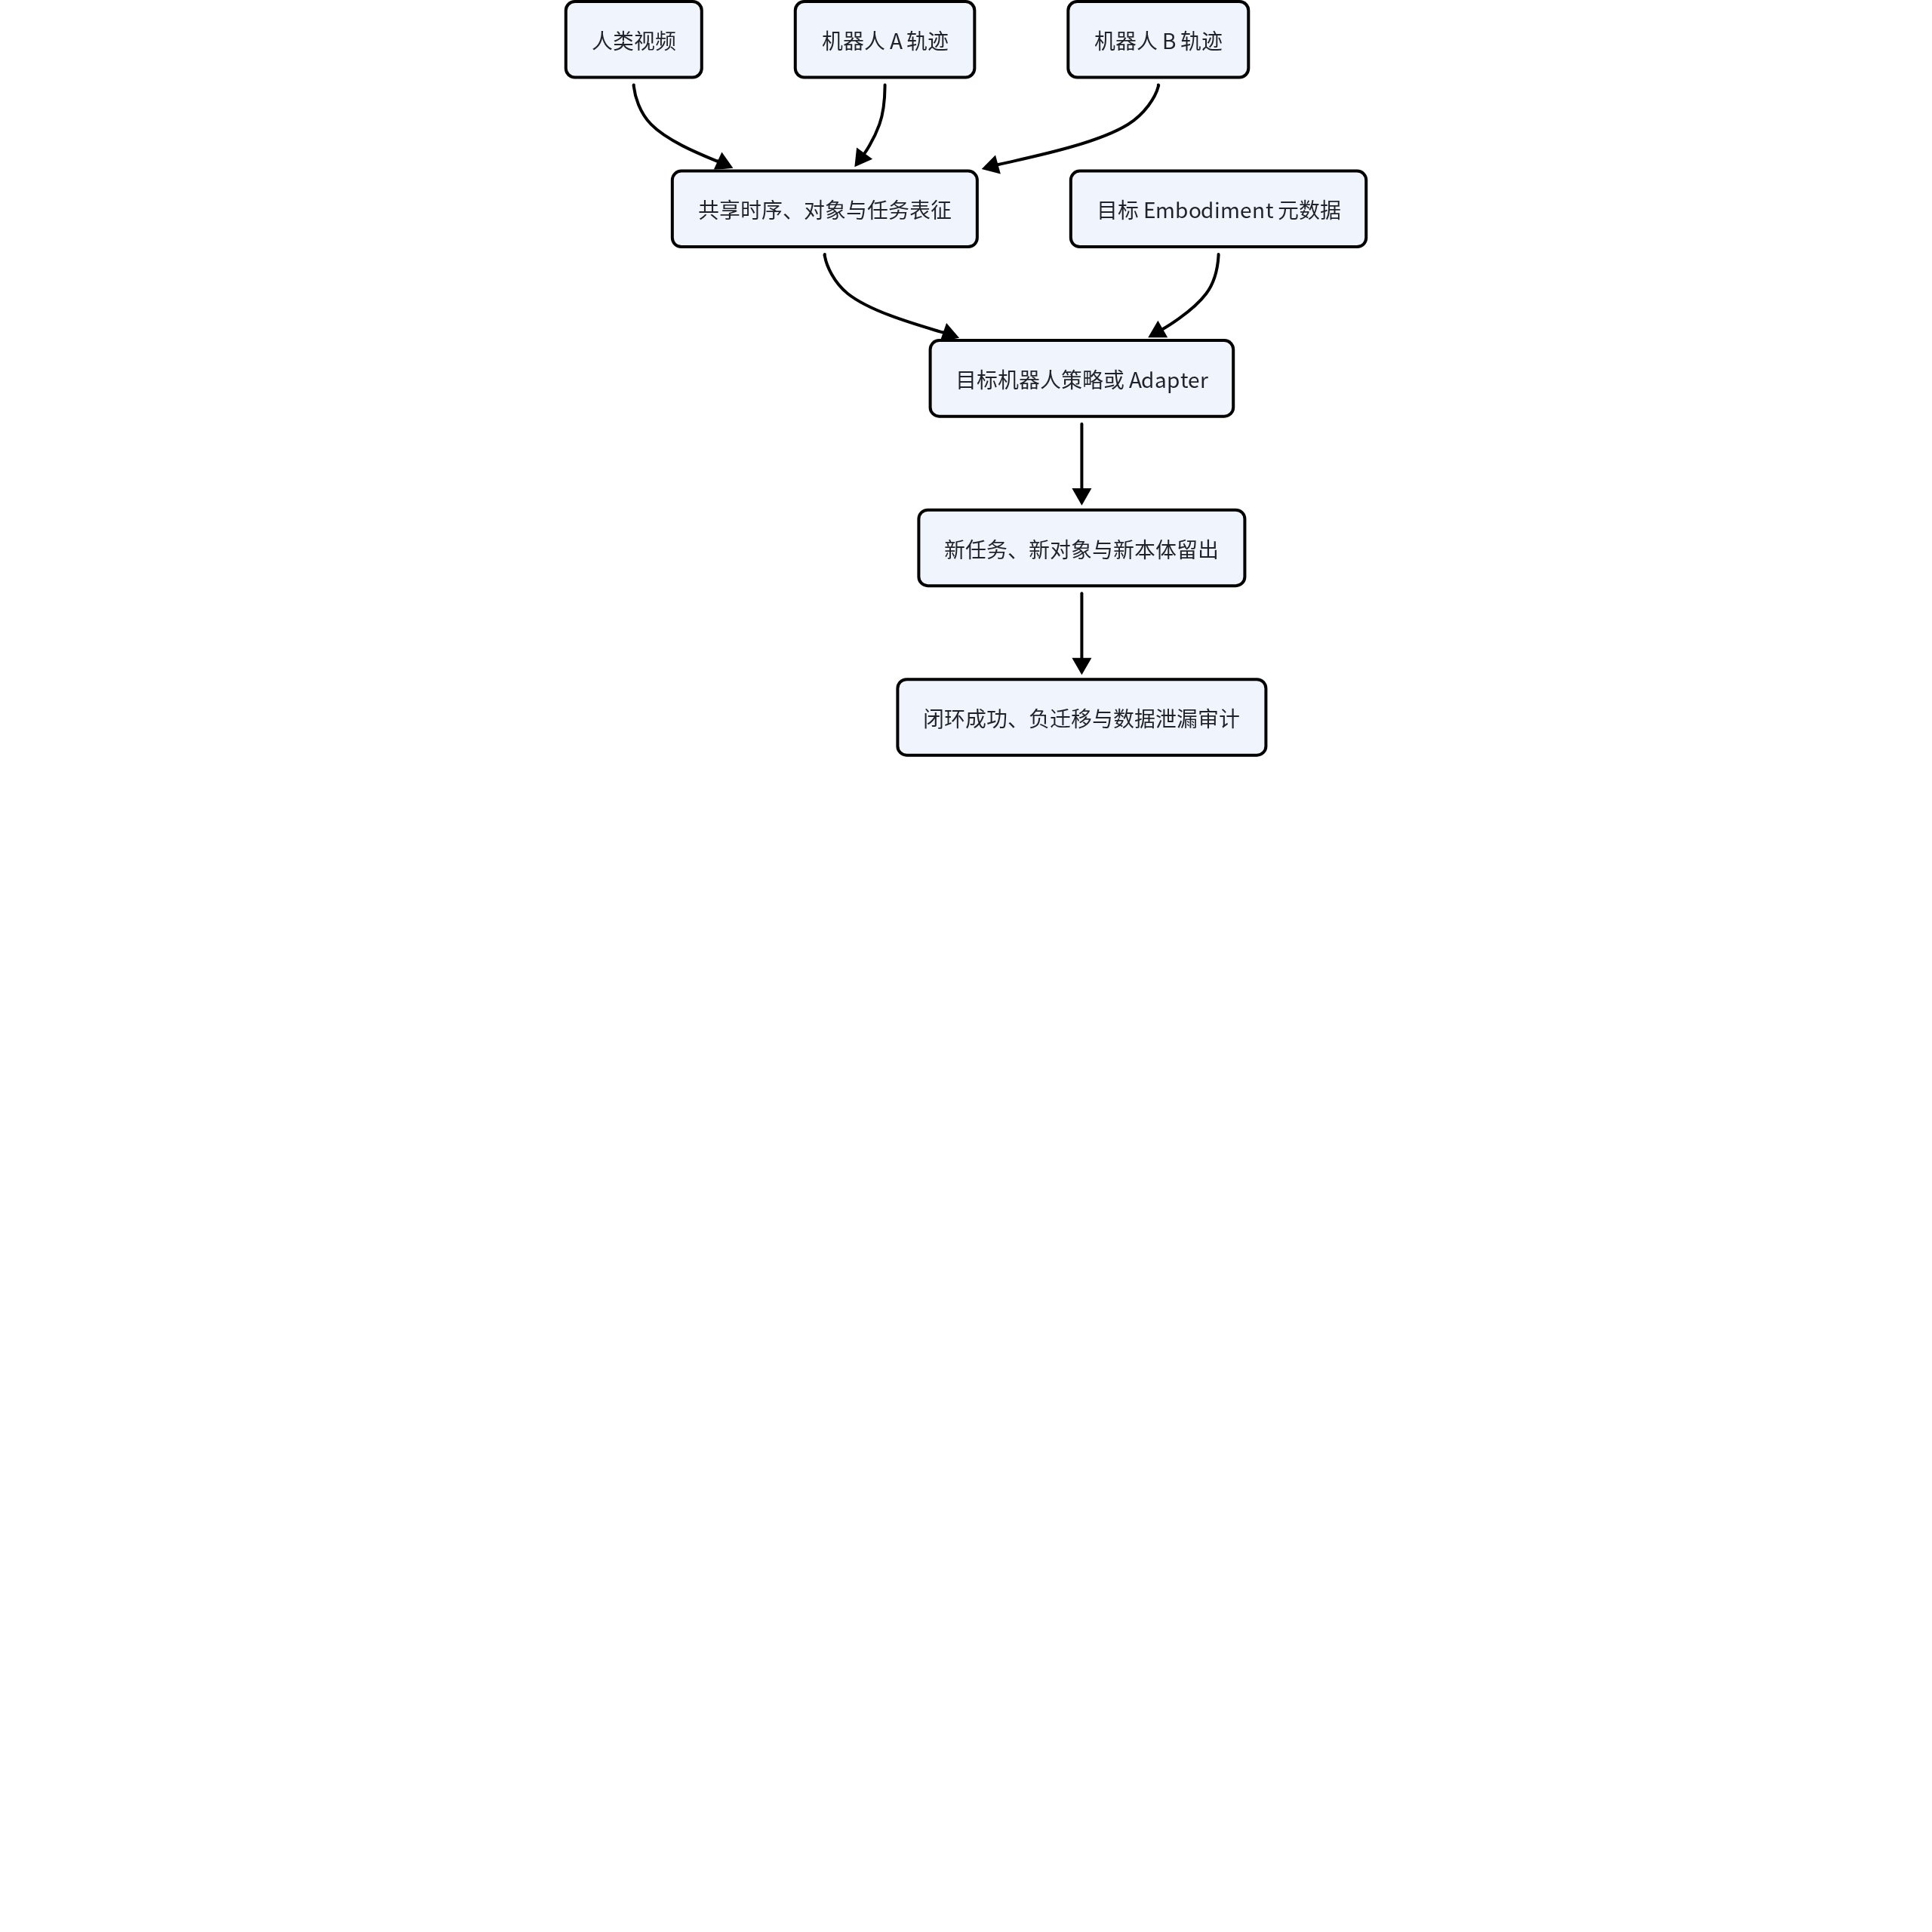
Minimal Experiment: Unified Reproduction Protocol
Fix the amount of labeled target-robot data, model capacity, total training compute, and inference budget, then incrementally add human video, data from other robots, and different intermediate variables. Objects, task compositions, and target embodiments must be independently held out, and curves of target-data volume versus success rate must be reported.
- Fix the amount of labeled target-robot data, then incrementally add human video and data from other robots.
- Compare visual pretraining, temporal contrastive learning, latent actions, explicit retargeting, and direct co-training.
- Use three independent holdouts: objects, task compositions, and embodiments.
- Plot target-data volume against success rate to test whether external data improves sample efficiency rather than merely increasing total compute.
Lab Exercises
- Construct a counterexample in which the latent representation can identify the data source but cannot transfer the task.
- Explain why future-frame prediction may learn motion without necessarily learning executable actions.
- Design an experiment that distinguishes object-centric transfer from memorization of the embodiment ID.
- Define three supervision signals for human video that do not rely on velocity labels, and identify their blind spots.
Major Failure Modes
| Failure | Manifestation | Unified diagnosis |
|---|---|---|
| Confounding from external-data scale | Performance improves after adding human video, but total compute and data also increase substantially | Fix compute, robot data, and model capacity |
| Substituting representation metrics for control | Linear-probe performance improves while robot success remains unchanged | Frozen-policy evaluation, few-shot curves, and real closed-loop evaluation |
| Task or object leakage | A supposedly novel embodiment has still seen the same scenes and action templates | Deduplicate at four levels: objects, tasks, scenes, and embodiments |
| Data-source classification shortcut | The latent representation can identify human versus robot data but cannot transfer the task | Compare adversarial data-source probes with target-task probes |
| Unstable human-motion retargeting | Kinematic tracking is accurate, but contact, balance, and force control fail | Dynamic feasibility, contact forces, fall rate, and control constraints |
| Infeasible visual plans | The future video appears plausible, but the target robot cannot reach the depicted state | Reachability, inverse dynamics, and real rollouts |
| Test-time memory contamination | Incorrect or irrelevant human videos degrade the current policy | Incorrect demonstrations, gating, shadow updates, and rollback |
Paper Facts, Authors’ Interpretations, and Course Assessments
| Work | Paper fact | Authors’ interpretation | Course assessment |
|---|---|---|---|
| R3M / VIP | Learns visual or value-related representations from human video and applies them to downstream robot tasks | Temporal and interaction signals in video can provide general-purpose visual priors | This demonstrates representation transfer; it does not justify claiming that robot action supervision has been obtained |
| MimicPlay | Human play provides high-level task guidance, while a small number of robot demonstrations support low-level execution | Hierarchical division of labor can leverage human data to improve long-horizon manipulation | The contributions of high-level plan quality, low-level robot data, and repeated objects should be disentangled |
| ATM / video planning | Predicts future point trajectories or visual futures and conditions the policy on futures in observation space | Motion trajectories and visual goals can serve as a compact planning space | It is necessary to verify geometric reachability, correct contact, and whether the policy actually uses the predictions |
| HumanPlus / OmniH2O | Uses human motion, motion capture, and retargeting to train whole-body control for humanoid robots | Human structural priors can expand humanoid robot skills | Similar embodiments reduce mapping difficulty, but dynamic balance, contact, and hardware constraints still require robot control data |
| WAM-TTT | Human-side context is written into fast memory at test time, while robot-task supervision updates the update rule | Current human demonstrations can support rapid adaptation | The key evidence consists of held-out environments, incorrect-demonstration controls, retention of old tasks after adaptation, and rollback |
Course Cross-Reading
E0|Data, Representation, and Cross-Embodiment Learning